
Gemini 4 Argon is the top-rated AI model on LMArena as of October 15, 2026, at 1524, and Claude Opus 5.5 is the strongest on an independent agentic-coding run, at 65.2% on Terminal-Bench 4.0. Argon costs $2/$10 per million tokens through November 30, half of Opus 5.5's $4/$20. Nine models make this list, and picking the wrong one for the job, not the wrong vendor, is where most teams now lose money.
I evaluate AI tools across 65+ portfolio companies, and the three weeks since this ranking's September 26 edition brought five frontier releases: Anthropic shipped Claude Sonnet 5.5 (September 28) and Claude Haiku 5.5 (October 7), OpenAI shipped GPT-6.1 Sol (September 29), Meta shipped Muse Wonder (October 12), and Google made Gemini 4 Argon generally available (October 13). Two of them enter the top three.
What Are the Best AI Models in October 2026, Ranked?
Gemini 4 Argon from Google is the top-ranked AI model as of October 15, 2026. It leads the LMArena text leaderboard at 1524 (read October 15, 2026), a score LMArena marks preliminary, with a ±9 interval on 4,904 votes. Claude Opus 5.5 from Anthropic ranks second here: #3 on LMArena at 1508 and #1 on the Vals AI Terminal-Bench 4.0 leaderboard at 65.15% (updated October 13, 2026). Meta's new Muse Wonder is third, Claude Fable 5.1 fourth and GPT-6 Astra fifth. Gemini 3.8 Flash is the cheapest model in LMArena's top 10.
Claude Sonnet 5.5, Gemini 3.8 Flash, Meta's Muse Spark 1.3 and OpenAI's GPT-6.1 Sol round out the nine. The top of LMArena is tight: Muse Wonder (1509) and Opus 5.5 (1508) are a statistical tie, and the superseded Claude Fable 5 still sits #4 at 1504. Treat a gap of a few points as a tie. Track the category leader for your specific task, not the vendor brand, when picking a model for a new build.
The 9 Best AI Models in 2026, Ranked (as of October 15)
Ranking order: LMArena text score (each model's best-scoring variant), with two adjustments: Claude Opus 5.5 is placed above Muse Wonder, one LMArena point ahead of it, on its much higher Vals AI Terminal-Bench 4.0 score, and GPT-6 Astra and Claude Sonnet 5.5 are placed on their Terminal-Bench 4.0 results (third and second) despite ranking #30 and #36 on LMArena. Sources for the ranking: LMArena ranks and scores from the LMArena text leaderboard (read October 15, 2026). Independent Terminal-Bench 4.0 scores from Vals AI (updated October 13, 2026). Gemini 4 Argon from Google's model page, its GA date from the Gemini API changelog and pricing from Gemini API pricing. Muse Wonder from Meta's launch post and developer page. Claude Opus 5.5 from Anthropic's Opus 5.5 announcement; Claude Sonnet 5.5 from Anthropic's Sonnet 5.5 announcement; Claude Fable 5.1 from Anthropic's Fable 5.1 page and MacRumors; Claude pricing and context from Anthropic's models overview. GPT-6 Astra pricing and context from OpenAI's model docs, release date from the GPT-6 Astra system card, OpenAI-reported benchmarks via DataCamp. GPT-6.1 Sol from OpenAI's model docs and API changelog. Muse Spark 1.3 from Meta's developer page, release date from Meta's launch post. Gemini 3.8 Flash from Google's launch post and Gemini API docs.
Benchmark Scores Compared: Terminal-Bench 4.0
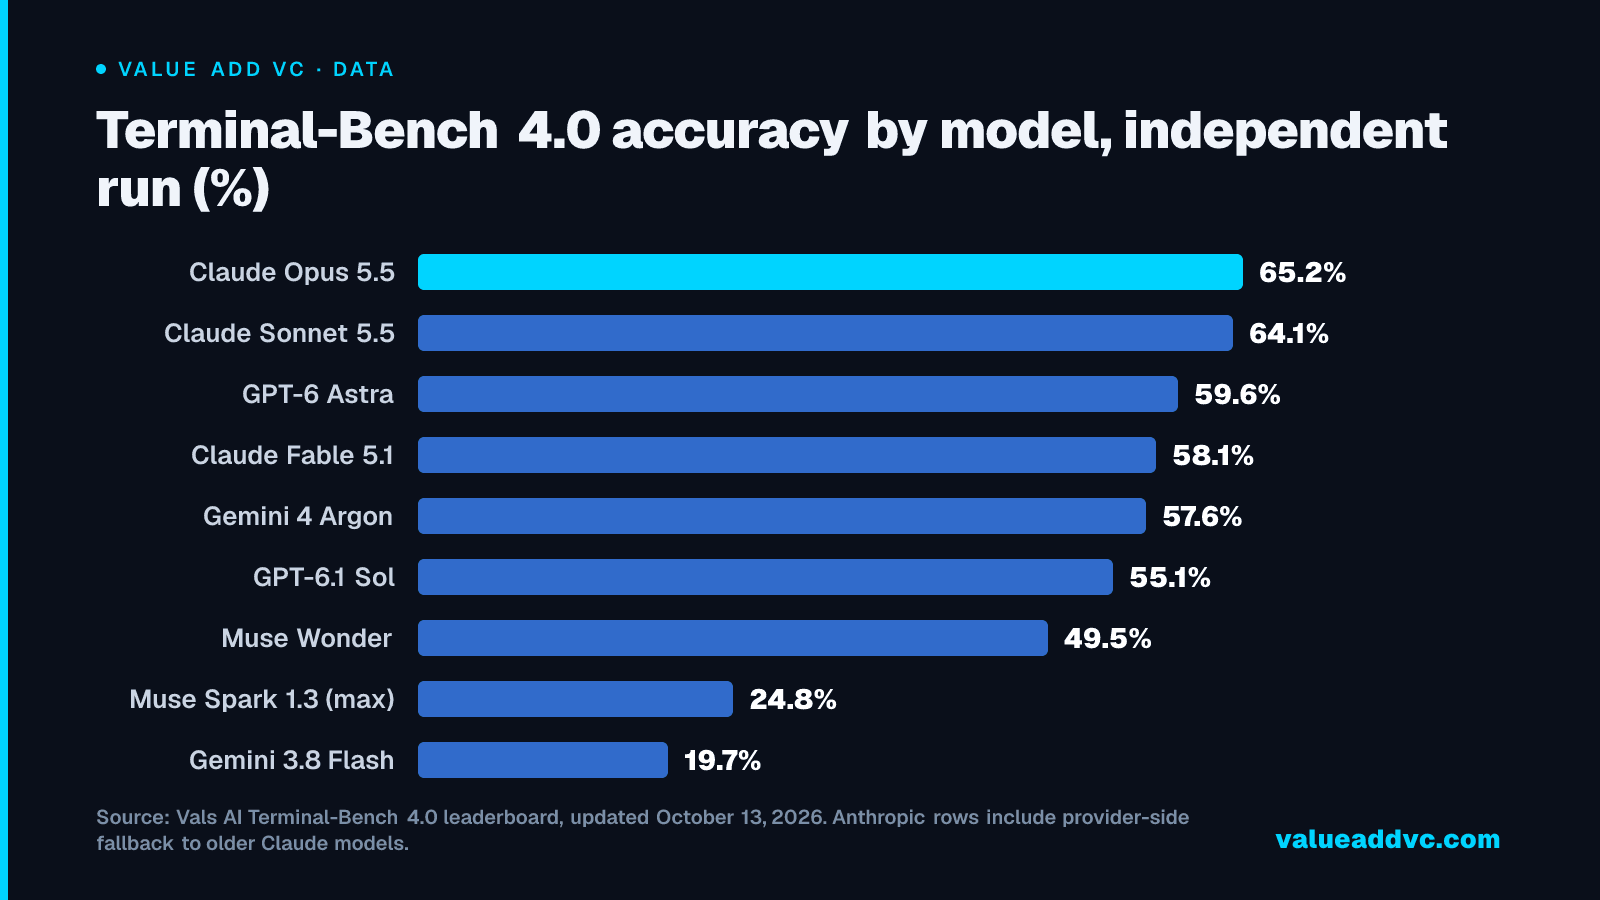
The September and October 2026 launches mostly stopped reporting SWE-bench Verified, so this chart uses Terminal-Bench 4.0. It shows the only independent run we could find: Vals AI's Terminal-Bench 4.0 leaderboard, updated October 13, 2026. One caveat from Vals: 22 of Opus 5.5's 198 task attempts were served by Opus 5 or Opus 4.8 through provider-side fallback, and counting those as failures lowers it from 65.15% to 58.08%, behind Claude Sonnet 5.5 (62.63% on the same basis) and GPT-6 Astra; Fable 5.1 drops to 50.00%. Vendor-run numbers are higher: Anthropic reports 66.4% for Opus 5.5 and 55.8% for Fable 5.1, and 70.6% for Sonnet 5.5.
Terminal-Bench 4.0 accuracy by model, independent run (%)
Vals AI Terminal-Bench 4.0 leaderboard, updated October 13, 2026. Anthropic rows include provider-side fallback to older Claude models.
Data
| Item | Value |
|---|---|
| Claude Opus 5.5 | 65.2% |
| Claude Sonnet 5.5 | 64.1% |
| GPT-6 Astra | 59.6% |
| Claude Fable 5.1 | 58.1% |
| Gemini 4 Argon | 57.6% |
| GPT-6.1 Sol | 55.1% |
| Muse Wonder | 49.5% |
| Muse Spark 1.3 (max) | 24.8% |
| Gemini 3.8 Flash | 19.7% |
On the older SWE-bench Verified benchmark, the highest published score among models in this post or their predecessors is still the superseded Claude Opus 5's 96.0%, followed by Claude Fable 5 at 95.0%, Claude Sonnet 5 at 85.2% (Anthropic's Claude Sonnet 5 system card), GPT-5.6 Sol at 82.2% and Gemini 3.1 Pro at a Google-reported 80.6%. None of the September or October 2026 releases in this ranking has a SWE-bench Verified figure in the sources we checked.
Which AI Model Is the Best Value in 2026: Price vs Performance
Price separates these models more than capability does. Output pricing runs from Gemini 3.8 Flash's introductory $3.75 per million tokens to $50 for Claude Fable 5.1 and GPT-6 Astra, a spread of more than 13x, while the LMArena gap between #1 and #10 is 30 points. Here's the full side-by-side.
| Model | Input / Output ($/1M tokens) | LMArena text (rank) | Terminal-Bench 4.0 | Context window | Rank |
|---|---|---|---|---|---|
| Gemini 4 Argon | $2 / $10* | 1524 (#1, preliminary) | 57.6% Vals | 1,048,576 | #1 |
| Claude Opus 5.5 | $4 / $20 | 1508 (#3) | 65.2% Vals (58.1% excl. fallback); 66.4% Anthropic | 1M | #2 |
| Muse Wonder | $4 / $20 | 1509 (#2) | 49.5% Vals | 1M | #3 |
| Claude Fable 5.1 | $10 / $50 | 1502 (#6) | 58.1% Vals (50.0% excl. fallback); 55.8% Anthropic | 1M | #4 |
| GPT-6 Astra | $10 / $50† | 1477 (#30) | 59.6% Vals | 1,050,000 | #5 |
| Claude Sonnet 5.5 | $2 / $10 | 1475 (#36) | 64.1% Vals (62.6% excl. fallback); 70.6% Anthropic | 1M | #6 |
| Gemini 3.8 Flash | $0.75 / $3.75* | 1496 (#9, preliminary) | 19.7% Vals | 1,048,576 | #7 |
| Muse Spark 1.3 | $1.25 / $4.25 | 1494 (#10) | 24.8% Vals (max) | 1M | #8 |
| GPT-6.1 Sol | $2 / $10† | 1484 (#22) | 55.1% Vals | 1,050,000 | #9 |
*Gemini 4 Argon's $2/$10 runs through November 30, 2026, then $4/$20; Gemini 3.8 Flash's $0.75/$3.75 is introductory through December 31, 2026, then $1.50/$7.50 (Gemini API pricing). †OpenAI prices GPT-6 prompts above 272K input tokens at 2x input and 1.5x output for the full request. LMArena scores were read on October 15, 2026; Vals AI Terminal-Bench 4.0 scores are as of October 13, 2026. Pricing and benchmarks change frequently, so verify current figures before committing production spend.
Superseded Since the September 26 Edition
Four models from the previous edition drop out. Claude Sonnet 5 (formerly #7) is replaced by Claude Sonnet 5.5 at the same $2/$10 price. GPT-6 Sol (formerly #8, #61 on LMArena at 1459) is replaced by GPT-6.1 Sol, also at $2/$10. Gemini 3.1 Pro (formerly #6, now #19 on LMArena at 1487) gives way to Gemini 4 Argon as Google's flagship reasoning model. Grok 4.7 (formerly #9) is still xAI's newest model but has fallen to #89 on LMArena at 1444 and scores 28.79% on Vals AI's Terminal-Bench 4.0, below every model in this edition except Gemini 3.8 Flash and Muse Spark 1.3. Claude Haiku 5.5, released October 7 at $0.10/$0.50 per million tokens for prompts up to 100,000 tokens, is the new low-cost Anthropic option but sits outside the top nine.
How We Ranked These
The order starts from the LMArena text leaderboard as read on October 15, 2026, counting each model's best-scoring variant. We made three deliberate adjustments. Claude Opus 5.5 sits one point behind Muse Wonder on LMArena, a statistical tie, so the tie is broken on Vals AI's independent Terminal-Bench 4.0 run, where Opus 5.5 leads at 65.15% to Muse Wonder's 49.49%. GPT-6 Astra (#30 on LMArena) and Claude Sonnet 5.5 (#36) are placed on their Terminal-Bench 4.0 results, third and second on that board. Every other model follows its LMArena order, one current model per vendor tier. Gemini 4 Argon's #1 LMArena score is marked preliminary, so its lead could narrow as votes accumulate. This is an editorial blend, not a formula, so the inputs are published above for you to re-weight. Vendor-reported benchmarks are labelled as such, and we used independent runs from Vals AI wherever one existed, because self-reported and independently run numbers diverge: Anthropic's 66.4% Terminal-Bench 4.0 figure for Opus 5.5 comes down to 65.15% in Vals AI's run, and its 70.6% for Sonnet 5.5 comes down to 64.14%. Where no source published a number, the table says "not published" instead of estimating one. Pricing was checked against each vendor's own API documentation on October 15, 2026. Paid partners and affiliates never influence rank or inclusion. See our editorial standards.
Why the AI Model Rankings Keep Shifting in 2026
Three years ago, a new frontier model release moved the leaderboard for months. In September 2026 alone, Anthropic shipped Claude Fable 5.1 (September 1), Claude Opus 5.5 (September 22) and Claude Sonnet 5.5 (September 28). OpenAI shipped GPT-6 Astra (September 3), GPT-6 Sol and Luna (September 22) and GPT-6.1 Sol (September 29). Google shipped Gemini 3.8 Flash (September 2), Meta shipped Muse Spark 1.3 the same day, and xAI shipped Grok 4.7 on September 21. October kept the pace: Claude Haiku 5.5 (October 7), Meta's Muse Wonder (October 12) and Gemini 4 Argon, generally available October 13. That pace matters more than any single benchmark number: picking a model on brand reputation alone, rather than task-specific performance and current pricing, now leaves real accuracy and cost on the table.
It also means the "best model" question has split into separate questions: best for coding, best for autonomous agents, best for cost and best overall reasoning. Unlike the September edition, the LMArena leader and the independent agentic-coding leader are now different models: Gemini 4 Argon tops crowd preference, while Claude Opus 5.5 and Sonnet 5.5 hold the top two Terminal-Bench 4.0 scores. GPT-6 Astra leads the math and ARC-AGI-3 results OpenAI published, and the cheapest options sit near the top of LMArena but score far lower on independent Terminal-Bench 4.0: 24.75% for Muse Spark 1.3 and 19.70% for Gemini 3.8 Flash. Treat each benchmark as measuring a genuinely different capability, not a proxy for overall quality.
What the headline misses
A benchmark table implies these models are equally available to build on, and they aren't always. Claude Fable 5, the model that topped this ranking's August edition, was unreachable worldwide for about 19 days in June 2026 after a US export-control directive suspended it, with no public warning before the suspension or guaranteed timeline for the redeployment that followed. GPT-6 Astra also rolled out to a limited set of organizations first. A team that had shipped a production dependency on Fable 5 in that window would have had to fail over to a different vendor with zero notice. This likely means the practical "best model" decision for anything customer-facing should weight platform stability and a credible fallback path at least as heavily as the top-line benchmark score, something none of the leaderboards cited above actually measure.
How to Choose the Best AI Model for Your Use Case
Start with the task, not the vendor. For coding agents and long-running agentic work, Claude Opus 5.5 is the strongest pick: it has the top independent Terminal-Bench 4.0 score at $4/$20 per million tokens, and Claude Sonnet 5.5 is within about a point of it at $2/$10. Step up to Claude Fable 5.1 only if your own evals show Opus 5.5 falling short. For hard reasoning, math and science, Gemini 4 Argon is the new first test, at $2/$10 through November 30 and $4/$20 after. If you need an OpenAI primary, GPT-6 Astra is the strongest on Terminal-Bench 4.0 and GPT-6.1 Sol the cheapest per task. For high-volume work where frontier reasoning is overkill, Gemini 3.8 Flash at an introductory $0.75/$3.75 and Muse Spark 1.3 at $1.25/$4.25 both sit in LMArena's top 10 at a fraction of flagship prices. Budget for Argon's price doubling on December 1 and Gemini 3.8 Flash's on January 1, 2027.
For portfolio companies still deciding between a single-vendor commitment and a routing layer, I recommend routing by default once monthly API spend crosses roughly $5,000/month. Below that threshold, engineering time spent building a router usually costs more than the token savings justify. Above it, a lightweight router that sends coding and agent tasks to Opus 5.5 or Sonnet 5.5 and bulk tasks to Gemini 3.8 Flash, GPT-6 Luna or Claude Haiku 5.5, with a second vendor such as GPT-6 Astra or Gemini 4 Argon as a documented fallback, cuts blended cost versus single-vendor lock-in. The fallback also protects against a repeat of the Fable 5 export-control gap.
Track how these model economics flow into startup valuations on the AI Valuations Dashboard and how the hyperscalers funding this buildout are reporting results on Big Tech Earnings at Value Add VC.
What AI Model Benchmarks Actually Measure
Terminal-Bench 4.0, the coding benchmark behind the chart above, measures whether a model can operate autonomously inside a command-line environment across many sequential steps without a human checking each one. That means installing dependencies, debugging a failing build and recovering from its own mistakes. Scores are far lower than on older benchmarks because the tasks are harder: even the leader, Claude Opus 5.5, completes about 65% in Vals AI's run.
SWE-bench Verified, which drove this ranking's earlier editions, tests models against real GitHub issues pulled from popular open-source repositories. The model has to read the codebase, understand the bug report and produce a patch that passes the project's actual test suite. With the best published scores at 95-96%, it no longer separates frontier models, which is one reason the September and October 2026 launches reported Terminal-Bench 4.0 instead.
LMArena's score works differently again. It is a crowdsourced head-to-head preference ranking, not a task-completion score, generated from blind pairwise comparisons submitted by real users. It captures something closer to "which answer do people prefer reading," which is why GPT-6 Astra can be third on Terminal-Bench 4.0 while sitting #30 on LMArena. Use LMArena as a general-quality signal and the task-specific benchmarks as the actual purchasing decision. That leaderboard is now a venture-backed business in its own right: Arena, the company running it, raised a $200 million Series B in October 2026 at a $3.1 billion valuation — see our breakdown of the round and the business behind the board.
The Bottom Line
There is no single best AI model for every job in 2026, and as of October 15 crowd preference and independent agentic-coding scores point to different leaders.
Gemini 4 Argon leads LMArena, Claude Opus 5.5 leads agentic coding, and Gemini 3.8 Flash wins on price. Pick by workload, not by brand loyalty.
Track AI company valuations and the hyperscaler capex funding this model race on the AI Valuations Dashboard at Value Add VC. Originally published in the Trace Cohen newsletter.
Latest from the Pulse
Get VC data most people never see
— free to subscribe
Trace's notes on venture, AI and startups, a few times a week. Join 5,000+ subscribers. No spam.
No spam, unsubscribe anytime. Sent via Substack · Privacy · or subscribe on Substack ↗